PDF to Production

Join the next cohort.

Build reliable document applications. Join the waiting list and we’ll email you when the next cohort opens.

Get next cohort updates and stay up to date on everything about taking PDFs to production.

Full-day live workshop · Recordings included

Build Reliable Document Applications

Parse PDFs, retrieve evidence, extract information, and evaluate the results.

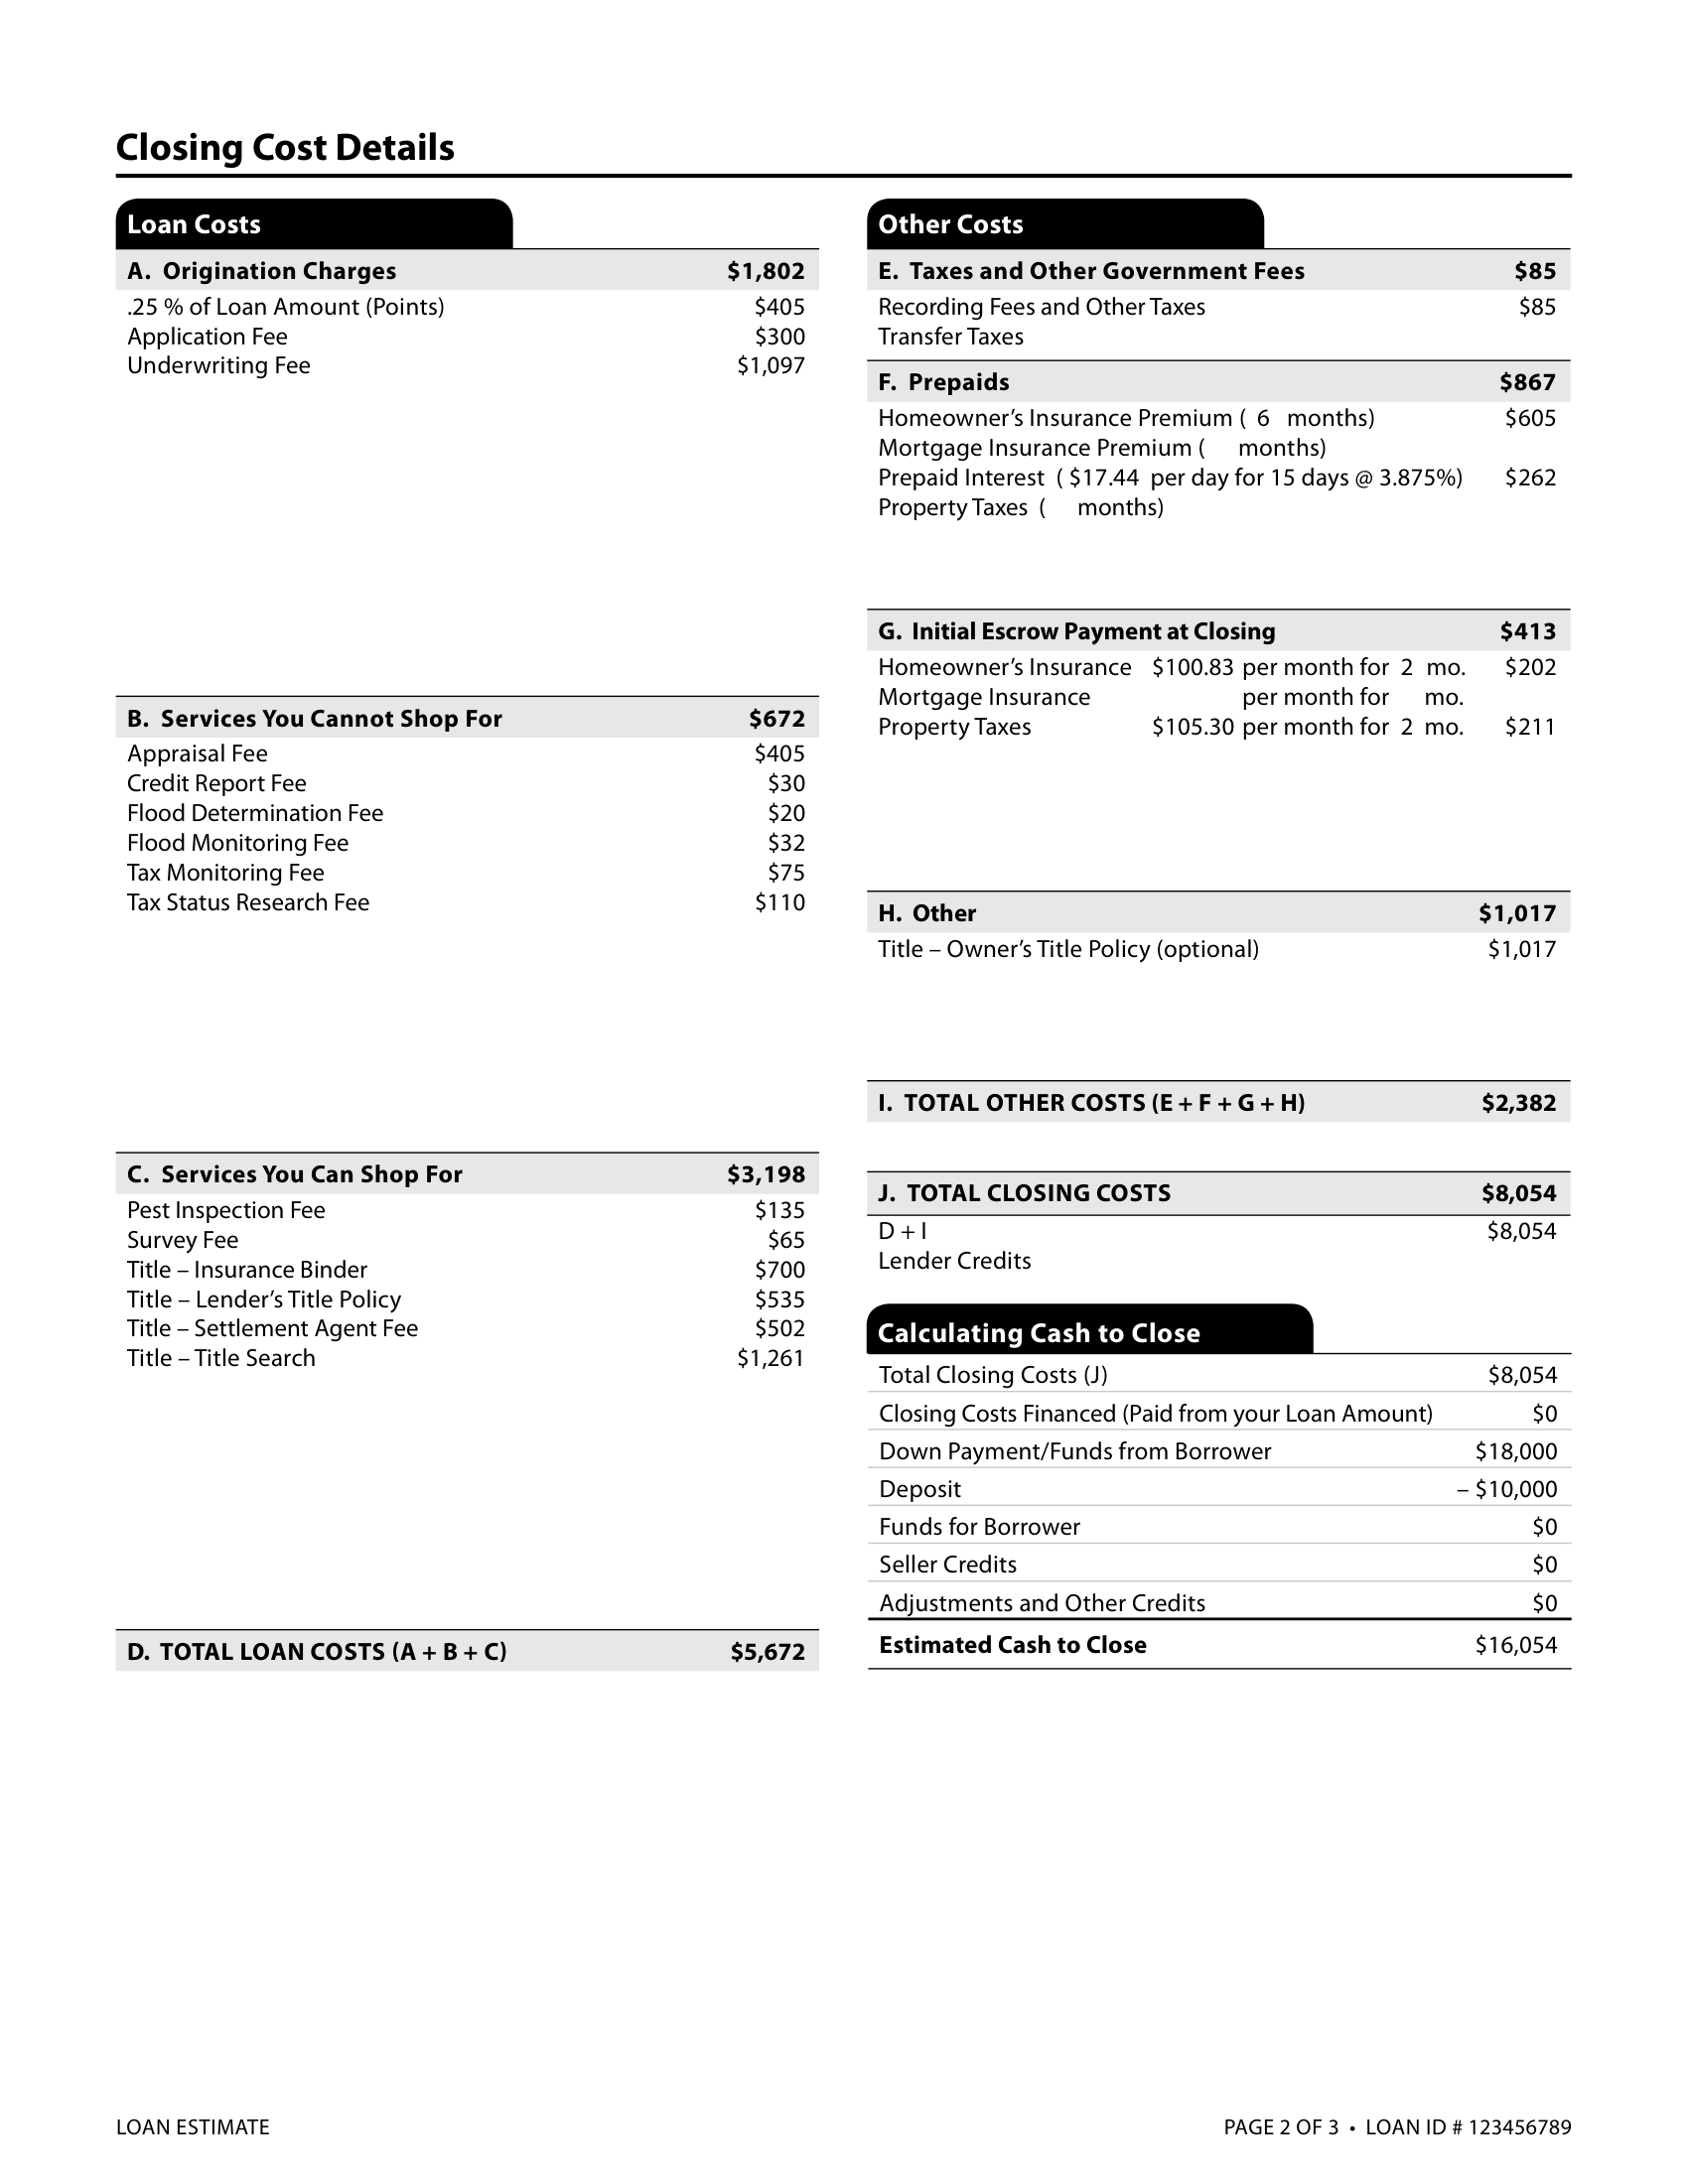
Loan estimate closing-cost tables
Source PDF“2 months”
OCR output“23”

Examples we discuss

Course examples and selected participant submissions.

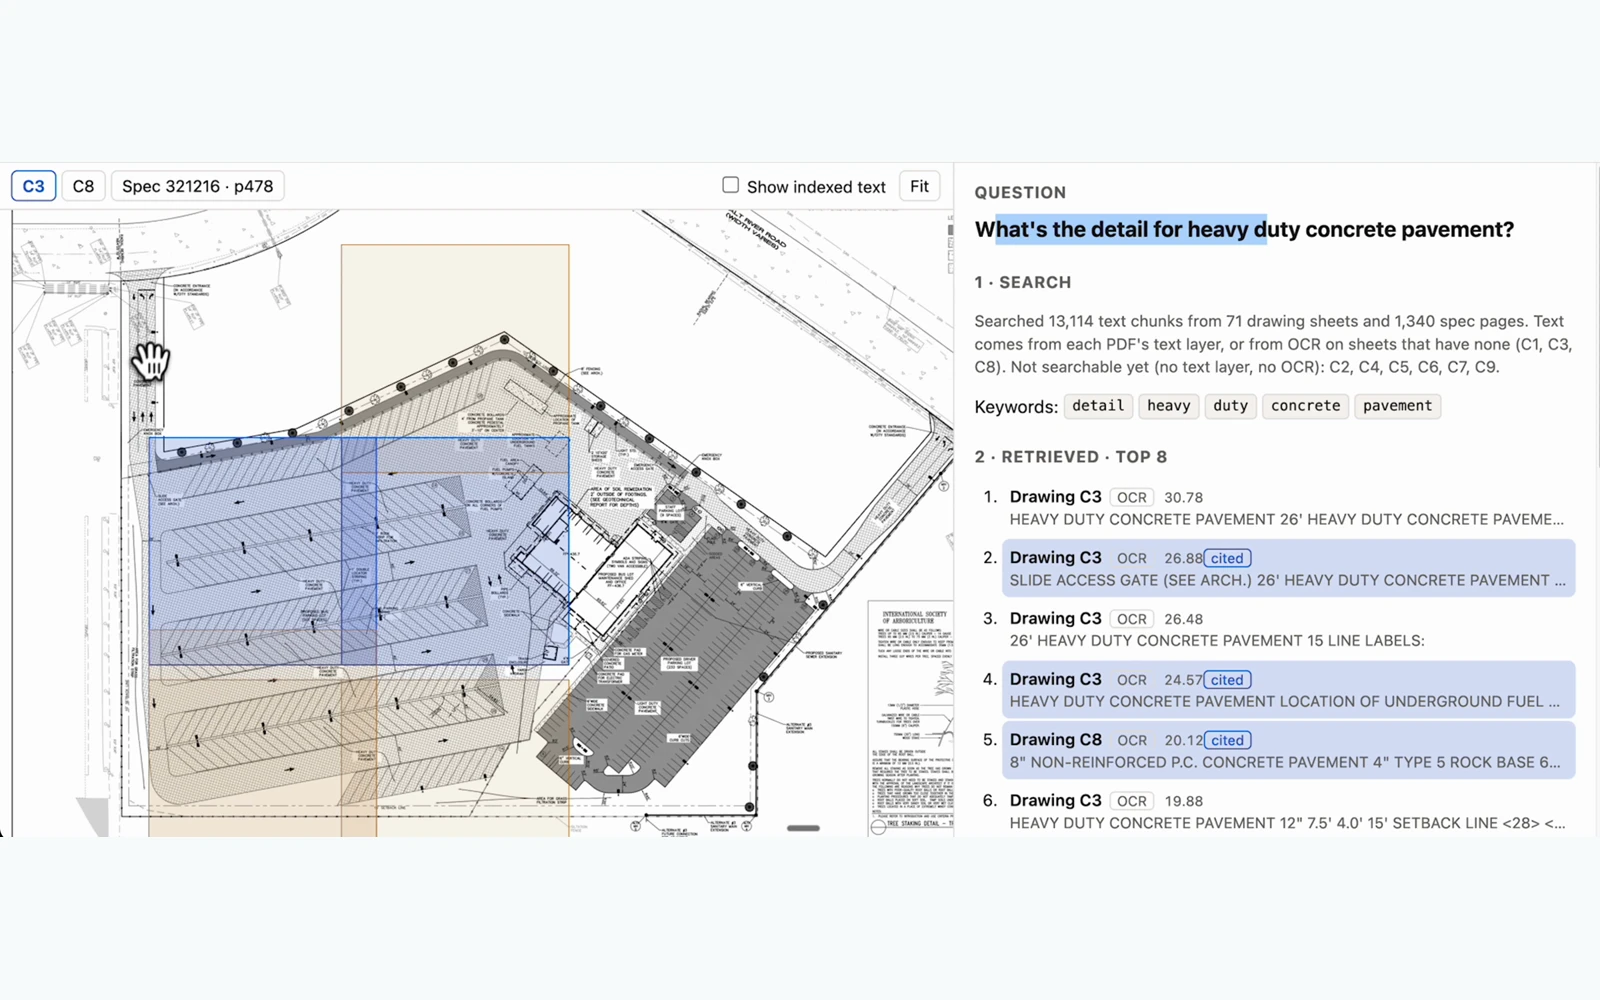
Blueprint review app showing highlighted drawing regions beside retrieved evidence

Blueprints

Find details across drawings and check source citations.

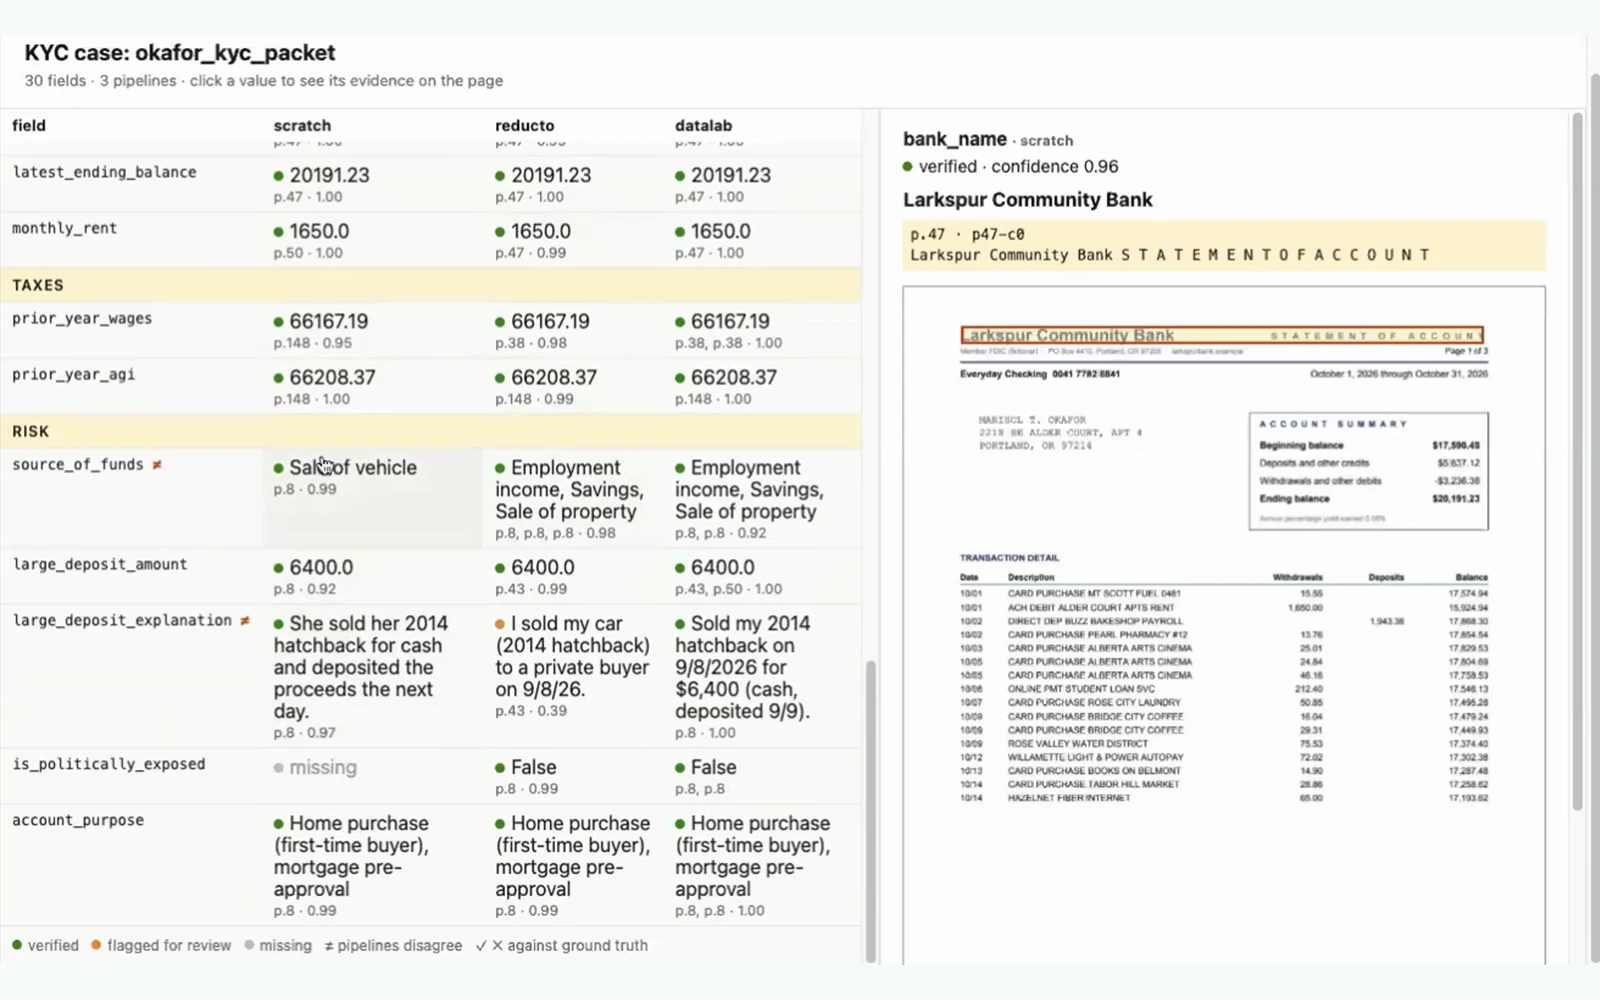
KYC review app comparing extracted fields from three pipelines alongside a bank statement with highlighted evidence

Customer documents

Extract information across a packet and check the supporting evidence.

Instructors

Isaac Flath

Isaac Flath

AI products · Education and research

Isaac has spent the last 10 years building AI products and has taught more than 4,000 students in courses on retrieval, evaluation, AI-assisted coding, and production AI systems. His work focuses on document processing, evals, traces, and the product workflows around them.
isaacflath.com

Joe Barrow

Joe Barrow

Senior Research Scientist · Adobe Research

Joe trains and serves vision-language models for document tasks. He previously led the machine learning team at Pattern Data and earned his PhD from the University of Maryland.

jbarrow.ai

Isaac’s students have included engineers and technical leaders from:

Microsoft
LinkedIn
Red Hat
Accenture

Previous cohort: curriculum & schedule

Here’s what we covered in November. Dates and details for the next cohort will be announced by email.

November 2026 cohort

Saturday, November 14, 2026

9:45 AM – 6:00 PM EST

Four core sessions · 45-minute lunch · KYC extraction lab and Q&A

  1. Kickoff & Parse

    • See how broken text layers, scans, reading order, and tables cause parsing errors
    • Compare text extraction, OCR pipelines, and vision-language models
    • Compare hosted APIs and self-hosted models on your own documents
    • Build a sample of 50–100 pages to compare accuracy, speed, and cost
  2. Break

  3. Retrieve

    • Compare keyword search, embedding search, and hybrid search
    • Use decision models to create facets for filtering pages, such as document type, person, or year
    • Tune decision thresholds using examples from your documents
  4. Lunch

  5. Extract

    • Extract document information into a defined schema
    • Link each answer to supporting text or a location on the PDF
    • Distinguish values written on the page from conclusions drawn from it
    • Use rules and decision models to check answers and send uncertain results for human review
  6. Break

  7. Evaluate

    • Review source documents and model outputs together
    • Find errors in parsing, retrieval, and extraction
    • Choose evaluation metrics for your task
    • Build tests from errors you find
    • Check whether automated evaluations agree with your own review
  8. Break

  9. Lab: Build a know-your-customer extraction pipeline

    • Work through a customer document packet to extract identity, employment, income, and banking information
    • Use decision models to select relevant pages and check extracted answers
    • Compare a custom pipeline with vendor options using the same documents and extraction schema
    • Review results alongside the source PDF, including supporting evidence, missing values, and answers flagged for review

Build and evaluate document applications on real PDFs.Get notified when the next cohort opens

Join the waiting list →

“Practical tips and good examples in repos that helped make the recommendations more tangible.”

Robin TullyCTO, Forecast.ingFeedback from Isaac’s previous live course

What’s included

30 days of follow-up support included

Four weekly office-hours sessions to help you apply the workshop to your own documents and system.

Unlimited async questions are included for 30 days after the workshop.

“Instructors are highly available for questions and advice and provide a ton of additional tutorials and walkthroughs.”

Mike PowersAI EngineerFeedback from Isaac’s previous live course
Can I submit my own PDF?

After registration, submit a PDF and describe what your product needs from it. We cannot review every submission live, so we’ll select participant PDFs for walkthroughs. That keeps the day grounded in the documents people are actually trying to put into production.

Do not submit confidential, regulated, or private material unless you have permission to share it. We will confirm how a selected example may be shown before using it with the cohort.

Do I need to code?

No. The lectures, examples, and Q&A do not require you to write or run code. The notebooks and code walkthroughs are optional: use them yourself, share them with an engineer, or give them to a coding agent when you’re ready to implement.

What happens if I cannot attend the full day?

Every session is recorded and the recordings are available after the workshop. You can return to any session you miss. You’ll also receive the notebooks and 30 days of follow-up support.

Included for enrolled students

  • Live instruction and Q&A
  • Afternoon labs with notebooks and instructor support
  • Option to submit your own PDF
  • Recordings and course materials available afterward
  • Four weekly office-hours sessions
  • 30 days of unlimited async questions
Student sign-in →